At a glance: Automated a manual AI governance intake process at SMBC using a multi-agent Copilot Studio workflow. Cycle time dropped from ~39 to ~20 days, admin effort per case from ~10 to ~2 hours, and weekly manual workload from 20+ to ~4 hours per person. Now used company-wide, replacing the original intake form entirely.
Overview
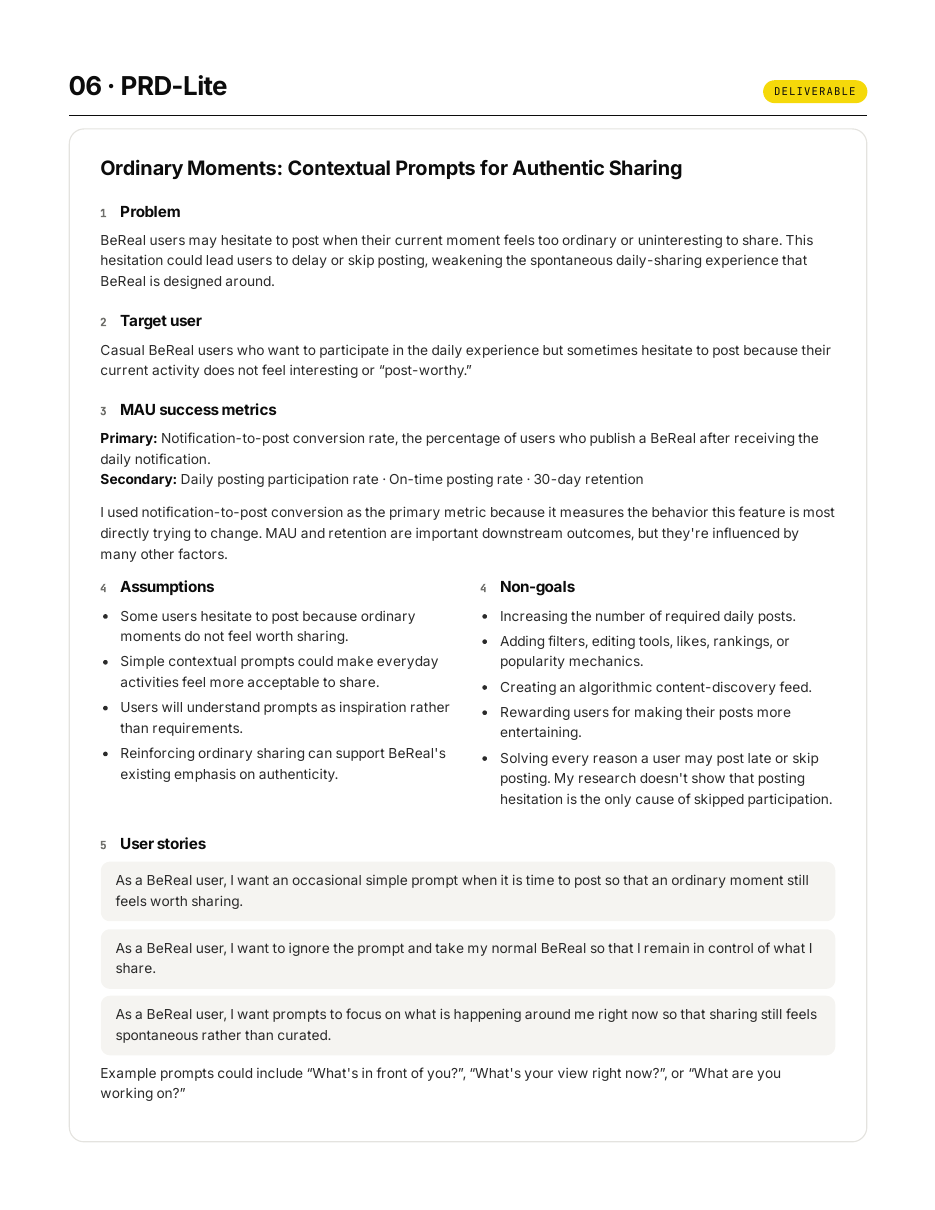
SMBC's AI Governance and Enablement (AIEG) team is the internal review board for every new AI use case at the bank. Before a team can use AI on anything, their request has to go through AIEG for intake, risk review, and sign-off. Before this project, the process was completely manual. A use case submission came in through an intake form roughly 60 questions long, and a team member had to review the entire thing by hand: checking for inconsistencies and missing information, then running downstream clarification with the use case owner over email and calls until the submission was actually complete. Once complete, the reviewer manually emailed the use case details to control groups like compliance and legal for approval, logged each group's “No Objection” in a tracker by hand, and built a presentation slide summary from a template as the last step before sending the case to the second line of approval. The team processes 200+ of these use cases a year this way, and the manual work added 20+ extra hours to each person on the team's workload every week.
| Friction | Root cause | Impact |
|---|
| Long, unstructured manual review | Intake form ran ~60 questions long with no automated pre-check for gaps or inconsistencies | A reviewer had to read every submission in full before even starting clarification, tedious and error-prone at 200+ cases a year |
| Manual clarification loop | Missing/inconsistent answers meant emails and calls back and forth with the use case owner | Multiple rounds per case, adding days to cycle time before a case was even ready for approval routing |
| Manual control-group routing | Reviewer manually emailed control groups (e.g., compliance and legal) and logged each “No Objection” in a tracker by hand | No shared system of record; status depended on someone remembering to update the tracker |
| Manual slide creation | Presentation summary was built from a template by hand as the last step before second-line approval | Repetitive formatting work added to the ~10 hours of admin time per case |
| Fragile tracking spreadsheet | Case status and control-group responses lived in one large Excel file, edited by multiple people at once | Tables and columns regularly collapsed under concurrent edits, and values could be overwritten with no audit trail |
Over a 9-week project during my AIEG internship, I automated AIEG's intake system: a multi-agent workflow in Copilot Studio that automates the intake, research, and clarification steps of the process while keeping a human reviewer in the loop for judgment calls. I designed, built, and tested it, then took it through review with my manager, the AIEG team, and IT/security before presenting it to CDAO AI Strategy leadership for final sign-off ahead of company-wide rollout. The project was also featured in SMBC's internal monthly AI newsletter.
After a pilot batch of cases ran through the new system, average cycle time dropped from ~39 days to ~20 days, admin effort per case dropped from ~10 hours to ~2 hours, and case traceability went from roughly half-manual to fully automated. Applying that same roughly 80% cut in admin effort to the 20+ hours a week the manual process added per person, the automated system brought that down to around 4 hours a week per person, a savings of about 16 hours a week per team member.
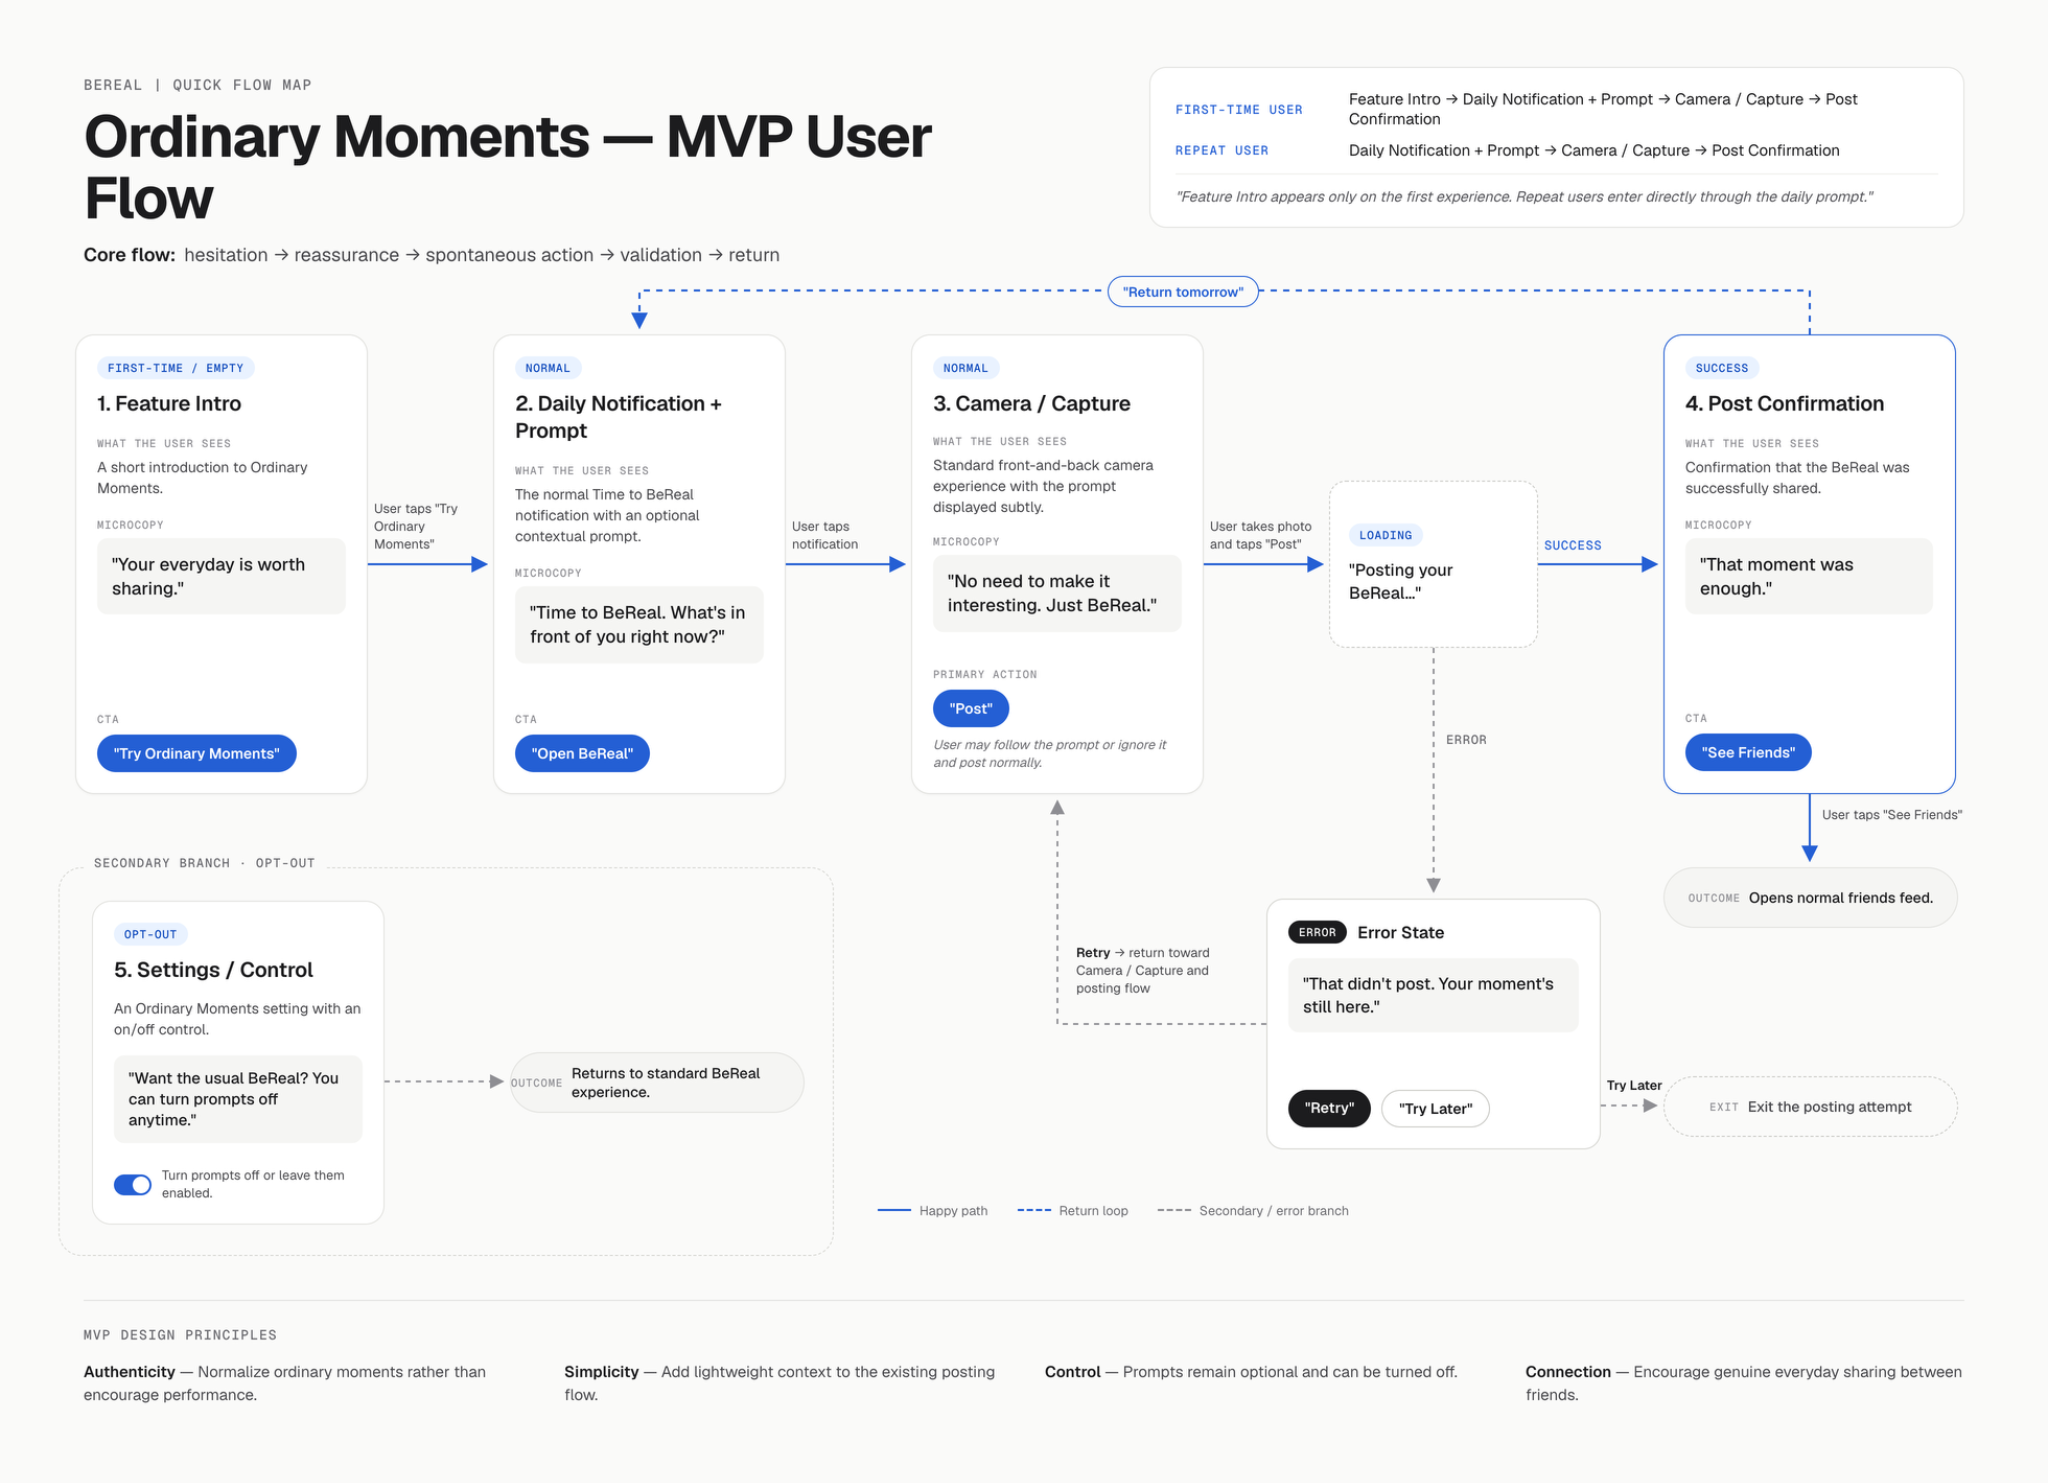
System flow, intake to approval
Use case owner submits
via Intake Assistant
chatbot
↓
Power Automate creates
row in Microsoft List
↓
Researcher Agent 1:
validates against rules
Incomplete or inconsistent↓Researcher Agent 2:
drafts clarification email
to Outlook drafts
↓Human reviewer sends
email
↓Researcher Agent 3:
monitors reply, auto-
updates datastore
↻ Complete↓Power Automate: fills
control group template +
drafts routing email
↓Power Automate:
generates presentation
slide from template
↓Human reviewer sends
routing email to control
groups
↓Writer Agent: monitors
inbox for No Objection
replies
↓Datastore updated with
control group sign-off
↓Case marked ready for
second-line approval
Discovery
I didn't want to design a solution for a process I only understood on paper. Before touching any automation, I spent time inside the manual process itself because I wanted to actually feel what the use case owners and reviewers were dealing with, not just hear about it secondhand. I shadowed the team as they worked existing intake cases, sat in on client calls where requesters described their AI use case, and eventually ran some of those calls myself so I understood the questions a reviewer actually needs answered, not just the ones on the 60-question intake form. I also worked a set of use cases end-to-end on my own, playing the role of an AIEG team member, because I wanted to find where the manual process actually broke down for the people living in it: which fields requesters always left vague, where clarification emails went back and forth two or three times, and where the reviewer had to go digging for context that should have been captured upfront.
Alongside that, I reviewed the history of past intake tickets to look for patterns across the 200+ case backlog, and stayed in constant back-and-forth with my manager and the rest of the AIEG team as the design took shape, checking my assumptions against how they actually made judgment calls. That input shaped which parts of the process could be automated outright (structured intake, clarification follow-ups, first-pass research) and which needed to stay a human call (risk judgment, edge-case exceptions).
Design decisions
The system, AIEG's AI Business Use Case Intake Automation Platform, is a multi-agent workflow built in Copilot Studio:
- Intake Assistant — collects the initial use case submission through structured guardrails and conversation flows, and structures it against a JSON schema so every request has the same shape regardless of how it was written. A Power Automate flow takes that output and creates a new row in the Microsoft List, which is what triggers the rest of the system.
- Researcher Agent 1 (validation) — checks the submission against a set of validation rules I wrote myself, based on what I learned diving into the manual process and talking to stakeholders during the first 2–3 weeks of the project.
- Researcher Agent 2 (clarification drafting) — takes Agent 1's output and drafts the clarification email, which lands automatically in the AIEG drafts folder in Outlook; a human still reviews and sends it.
- Researcher Agent 3 (reply monitoring) — watches the inbox for the use case owner's reply and automatically updates the datastore with whatever changed. If someone corrected a field, say switching “third-party data” to “internal data,” that update lands in the record automatically instead of someone re-keying it.
- Writer Agent — comes in after Power Automate has filled out the control group template, drafted the routing email in Outlook, and created the presentation slide from a template (more on that tradeoff below). The Writer Agent then watches the inbox for control group replies from legal and compliance, and when one comes back with “No Objection,” it records that in the datastore automatically instead of someone logging it in a tracker by hand.
The agents are connected through a JSON schema data layer and orchestrated with Power Automate, with SharePoint and Microsoft Lists for case tracking, Word template automation for the final governance writeup, and Adaptive Cards for reviewer interactions.
Agent architecture
JSON datastore /
Microsoft Lists
Power Automate, not agentsFill control group
template + draft routing
email→Generate presentation
slide
Copilot Studio agentsIntake AssistantResearcher Agent 1
ValidationResearcher Agent 2
Clarification draftingResearcher Agent 3
Reply monitoring
Writer Agent
Control group reply
monitoring
One decision I pushed for and had to defend to leadership: the original design called for two more writer agents, one to fill out the control group template email and one to generate the presentation slide. Partway through, I decided deterministic Power Automate logic was the better choice for both, since they're simple, repeatable formatting steps with no judgment involved, and swapped the agents out for Power Automate flows instead. That's why the final architecture has only one Writer Agent, handling inbox monitoring for control group replies, rather than three. More broadly, for well-defined, rule-based steps I chose reliability and lower maintenance cost over the flexibility of an agent we didn't actually need.
I also chose JSON as the canonical data model on purpose, even though it added upfront schema design work, because AIEG's four-project roadmap includes a future migration to ServiceNow, and a clean, portable data model now saves a much more painful re-architecture later.
I also migrated case tracking off a shared Excel file, where multiple people editing it at once regularly collapsed tables and columns and made it easy to overwrite someone else's entry, into Microsoft Lists, which gave the team real auditability and got rid of those failure modes entirely. While I was at it, I renamed every column: the old spreadsheet used the raw, long-form questions straight off the Microsoft Form (things like “What is the name of your use case?”), so I rewrote them as short, direct labels (“Use Case Name”) and checked every rename with each AIEG team member to make sure it was still intuitive to them before finalizing it.
The Microsoft Form itself no longer exists. It's been fully replaced by the Intake Assistant chatbot, which is now how everyone at SMBC submits an AI use case request.
Column rename, old spreadsheet vs. Microsoft Lists
| Old Excel column (raw form question) | New Microsoft Lists column |
|---|
| What is the name of your use case? | Use Case Name |
| What type(s) of data will this use case process? | Data Types |
| Who is the business owner of this use case? | Business Owner |
| What types of AI does your use case use? | AI Types |
Sample clarification email (actual system output, from testing)
Subject: [219] Generation Chatbot Clarification Follow-Up
Hi [Use Case Owner],
I hope you're doing well. Thank you for submitting your AI use case, Generation Chatbot. We need a few clarifications before we can finalize the intake and proceed with governance review.
Please respond to each concern using the same numbered list format above so we can review each clarification clearly.
1. Use Case Name
The submitted name is “Generation Chatbot,” which is too generic and repeats the process type without giving business context. Please provide a more specific, business-friendly name (no more than 5 words) that reflects the purpose described in your summary. Example: “Cybersecurity Software Onboarding Assistant.”
2. KPI Targets
Current KPIs show Baseline: 0 reports, Expected: 0 reports. Expected values should indicate improvement over the baseline. Please provide an updated expected KPI target. Example: Baseline: 0 reports, Expected: 10 reports.
Once you provide the requested updates, we can finalize the intake and engage the appropriate control groups for the next steps.
Please let us know if you need any clarification or examples to complete these items.
Kind regards,
AIEG Team
This is an actual clarification email the Researcher Agent drafted during testing, addressed automatically to the use case owner by name, pulled straight from the Business Owner field the Intake Assistant captured at submission, no one typed the greeting by hand. It also references the specific case number and the specific gaps it found (a vague use case name, KPI targets that showed no expected improvement over baseline), rather than a generic form email.
Risks & tradeoffs
- Risk: letting an agent make the actual risk-approval call would remove the accountability the whole governance process exists for. Design choice: agents handle intake, research, and clarification, but a human reviewer always makes the final judgment call and was the one who actually sent every email the agents drafted in Outlook, nothing went out automatically. I followed SMBC's own bank governance policies while building the system itself, since a tool meant to enforce governance has to hold itself to the same standard.
- Tradeoff: deterministic Power Automate logic vs. an LLM agent for the control-group template email and the presentation slide. Two more writer agents would have been more flexible, but less predictable and harder to debug; for formatting steps with no real judgment involved, I chose reliability and lower maintenance cost over flexibility we didn't actually need.
- Dependency: the Researcher Agent's usefulness depends on how well-organized AIEG's own historical case data is — messy inputs would have produced weak research output, so part of the build was cleaning up that foundation myself (see the Excel-to-Lists migration above).
Testing
Because I'd already run cases manually myself, I had a working sense of where things would go wrong before I ever tested the system — vague submissions, requests that touched multiple risk categories at once, requesters who didn't answer clarification emails, edge cases the original intake form didn't really account for. I put myself in each type of user's shoes (a first-time requester who doesn't know the process, a reviewer trying to move fast, a requester ignoring a clarification email) and built test cases around each, rather than only testing the happy path.
One concrete example: a use case came in named “Generation Chatbot” with KPI targets left at Baseline: 0, Expected: 0, a vague name and no measurable improvement target. Researcher Agent 1 flagged both as incomplete, and Researcher Agent 2 drafted the clarification email shown earlier under Design Decisions that named the exact problems and gave the owner examples of what a valid answer looked like, instead of a generic “please provide more information” message.
Before rollout, I ran a pilot batch of real cases through the system alongside the existing manual process, so I had a direct before/after comparison on the same kind of caseload rather than a projected estimate. That pilot is where the ~39-to-~20-day cycle time, ~10-to-~2-hour admin effort, and traceability numbers came from.
Results
| Metric | Before | After (pilot) |
|---|
| Average intake cycle time | ~39 days | ~20 days |
| Admin effort per case | ~10 hours | ~2 hours |
| Case traceability / auditability | ~50% manual | 100% automated |
| Requests in active queue | 200+ | (same volume, faster throughput) |
| Manual workload per person | 20+ hrs/week | ~4 hrs/week (~80% cut, ~16 hrs/week saved) |
| Adoption | Manual Microsoft Form | Form retired; every AI use case at SMBC is now submitted through the Intake Assistant chatbot |
Impact chart
Impact, as % of the manual baselineBefore After
0%20%40%60%80%100%120%
Cycle time: 39 to 20 days. Admin hrs/case: 10 to 2. Weekly workload: 20+ to ~4 hrs/person.
What I'd build next
If I'd kept working on this past the internship, the next thing I'd build is a final Evaluator Agent. It would check the whole use case end to end: confirm the submission was complete, confirm “No Objection” had come back from every control group, confirm the presentation slide was finished, and then mark the case complete so it could move on to the second stage of approval automatically, instead of a person doing that final check by hand.